TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Anthropic published a research post on Nov. 6, 2026, describing how Claude agents can save, organize and correct information between sessions. Its reported experiments suggest that selective notes and structured memory can help on some tasks, though the results are company-run evaluations and include single runs.
Anthropic published a research post on November 6 describing how its Claude models can save and use information between sessions, including notes, searchable structures and a process for correcting stored memories. The post reports that a newer model using a smaller set of organized notes earned more badges in a Pokémon Red test than an older model that created hundreds of files, while a separate company-document experiment showed higher scores with a self-built wiki.
Anthropic defines agent memory as knowledge gained through interactions or assigned tasks that a model retains between sessions in material it can read later. That differs from a model’s context window, which holds information available during the current session, and from changes to model weights during training. The post also distinguishes memory from summaries used to compress an ongoing conversation.
The system Anthropic describes includes memory notes, a judgment about which information is worth keeping, and a “dreaming” step in which an agent checks its notes against logs or transcripts and may correct or reorganize them. It also describes memory representations such as linked wiki pages, with a small top-level layer loaded at the start of a session and other material retrieved when needed.
In a Pokémon Red comparison at roughly 10,000 game steps, Anthropic reports that Claude Sonnet 3.7 created 413 files in 225 folders and had earned one badge. Claude Fable 5 created nine files in two folders, plus a top-level dashboard file, and had earned four badges. Anthropic also reports that a wiki built over 128 sessions raised performance on 25 questions about company documents from 13% to 48% of graded criteria. These are results from Anthropic’s own evaluations, not peer-reviewed findings.
Inside AI Agent Memory Research and Practical Experiments
Anthropic describes how agents can save, organize and review information between sessions. Its company-run experiments suggest structured memory may help on some tasks.
What agent memory means
Saved knowledge can be retrieved in later sessions, unlike information held only in the active context window.
- Available during the current session
- May not carry over when the session ends
- Selected information saved for later
- Can be organized and retrieved when needed
Keep useful knowledge
Anthropic says repeated screen details were redundant in the game test, while plans and tested strategies needed to be saved.
Save what matters
Preserve useful details, such as a deadline or a tested task rule.
Organize for retrieval
A small top-level layer can point agents to relevant material when needed.
Check stored notes
Between sessions, an agent can compare notes with logs and revise them.
What the experiments reported
In one Pokémon Red run per model, the newer model used fewer files and had earned more badges.
| Model | Memory files | Folders | Badges |
|---|---|---|---|
| Claude Sonnet 3.7 | 413 | 225 | 1 |
| Claude Fable 5 | 9, plus a dashboard file | 2 | 4 |
Limits and reader action
The results come from Anthropic’s own evaluations, not a peer-reviewed paper. The game comparison used one run per model, and the document result may not generalize to other tasks.
Why Selective Memory Matters
Information carried between sessions can shape an agent’s plans and decisions, so the way it is stored has practical consequences. A note that preserves a user’s deadline or a tested task rule may help later work; a mistaken or outdated note may steer the agent wrong. Anthropic’s post treats memory as a system that needs both selective writing and later review, rather than as a record of everything that happened.
The reported contrast in the game test also points to a difference between storing observations and retaining useful knowledge. Anthropic says information visible on the screen each turn was redundant, while plans and tested strategies needed to be recorded to remain available. The company-document result suggests that organizing material into linked pages may help answer questions, although the evaluation alone does not establish how well the approach works across other tasks or users.
Products Worth Considering

Apple MacBook Air 13.6-inch Laptop with M5 Chip, 16GB Memory, 512GB SSD, Sky Blue
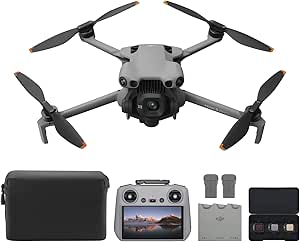
DJI Mini 5 Pro Fly More Combo with DJI RC 2

Bose SoundLink Plus Portable Bluetooth Speaker, Black
As an affiliate, we earn on qualifying purchases.
From Session Context to Stored Notes
Conventional chat sessions rely on the information present in the active context window. When a session ends, that working context may not be available to a later session unless the system saves material separately. Agent memory adds a storage and retrieval layer that can carry selected information forward.
Anthropic connects its proposed “dreaming” step to the idea of sleep-time compute, which researchers at Letta and the University of California, Berkeley have explored. In Anthropic’s account, the agent can use time between sessions to compare stored notes with source records, revise them and prepare information for future use. The post describes this as a design approach; it does not establish that agent memory works like human memory.
““knowledge that Claude gains from experience—including interactions with users and tasks it’s been assigned—and that it retains between sessions, saved as context it can read later.””
— Anthropic, in “The components of agent memory”
Limits of the Reported Tests
The reported evaluations were conducted by Anthropic and published as a research post, not a peer-reviewed paper. The Pokémon comparison involved one run per model, so the reported badge counts do not show how reliably the result would repeat. The post’s company-document result gives a score change across 128 sessions, but the material provided does not establish whether the same gain would appear on other document collections or question sets.
It is also unclear from the post how often stored notes are wrong, how much review costs in time or computing resources, and how well the “dreaming” process catches errors in practice. The experiments do not settle which memory structure is best across different agents and tasks.
Testing Memory Across More Tasks
The post presents memory notes, review between sessions and layered retrieval as components for agent builders to explore. Further evaluations would be needed to show whether the reported gains hold across repeated runs, different tasks and models, and to measure how often agents retain or correct useful information without preserving stale details.
For readers using memory-enabled assistants, the immediate practical point is to check what the system has saved when a remembered detail could affect a decision. Anthropic’s post describes ways an agent might review its notes, but it does not specify a general standard for user control, deletion or correction across products.
Key Questions
What does Anthropic mean by agent memory?
Anthropic defines it as knowledge an agent retains between sessions in material it can read later, including information gained from interactions and assigned tasks.
How is agent memory different from a context window?
A context window holds information available during the current session. Agent memory is saved separately so it can be retrieved in a later session.
What did Anthropic report in its Pokémon Red test?
In one run per model, Anthropic says Claude Sonnet 3.7 created 413 memory files across 225 folders and earned one badge; Claude Fable 5 created nine files in two folders plus a dashboard file and earned four badges.
Was the company-document result peer reviewed?
No. The results were published in an Anthropic research post, which the source material identifies as not peer reviewed. Anthropic reported a rise from 13% to 48% of graded criteria across 128 sessions using a self-built wiki.
Source: Thorsten Meyer AI